
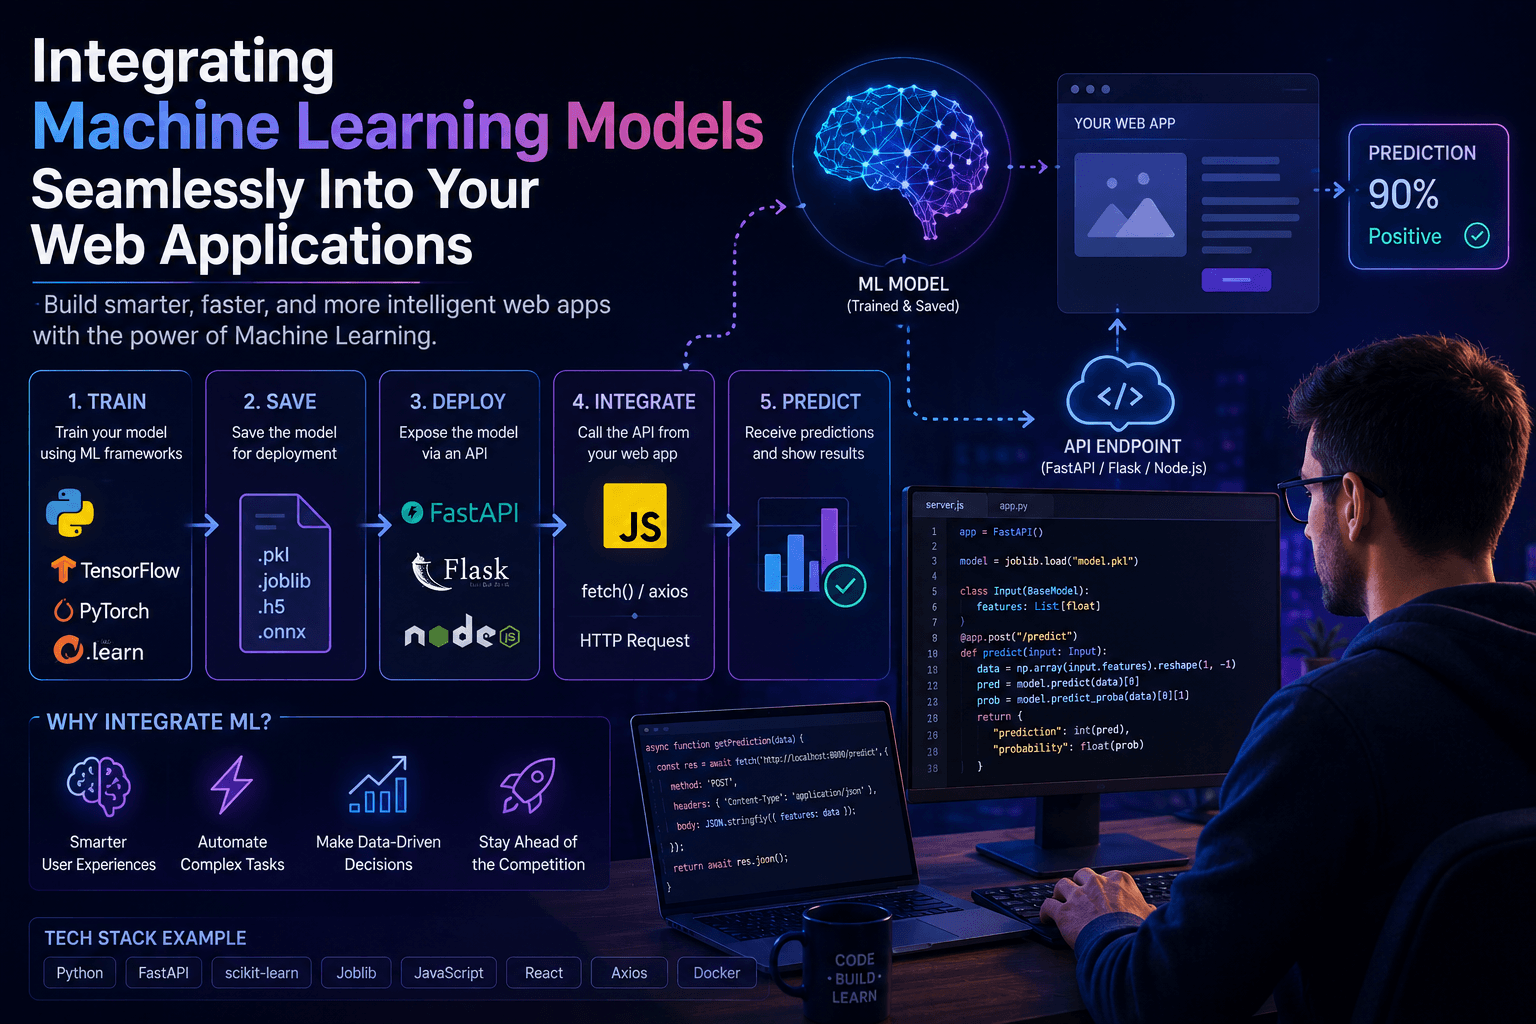
Machine learning is no longer limited to research laboratories or standalone data science notebooks. Today, developers can integrate trained machine learning models directly into web applications and use them to deliver intelligent features such as recommendations, fraud detection, image classification, sentiment analysis, demand forecasting, document processing, and personalized search.
However, taking a model from a Jupyter Notebook and putting it behind a production web application requires more than simply loading a .pkl or .onnx file. Developers need to think about API design, model loading, latency, scalability, security, monitoring, data validation, and deployment.
A practical architecture usually separates the user interface from the machine learning inference layer. The browser communicates with a backend API, and the API validates the request, prepares the input, runs the model, and returns a structured prediction.
This approach makes machine learning easier to maintain and allows the frontend and model-serving layer to evolve independently.
In this guide, you’ll learn how to integrate machine learning models into modern web applications, how to expose models through APIs, how to optimize inference performance, and which production practices can make an ML-powered application more reliable.
What Does Machine Learning Integration Mean?
A machine learning model is essentially a function that receives input data and produces a prediction or other output.
For example:
Input data → Machine Learning Model → Prediction
A web application adds another layer around that process:
User
  ↓
Web Browser
  ↓
Frontend Application
  ↓
Backend API
  ↓
Data Validation
  ↓
Machine Learning Model
  ↓
Prediction
  ↓
JSON Response
  ↓
Frontend
  ↓
User
Consider a house-price prediction application.
A user might enter:
- Property size
- Number of bedrooms
- Location
- Property age
- Number of bathrooms
The frontend sends those values to an API. The backend converts them into the format expected by the model, performs inference, and returns a predicted price.
The browser then displays the result.
This architecture is useful because the model does not need to be exposed directly to the public internet.
Why Use an API to Serve a Machine Learning Model?
One of the most common approaches is to wrap the model inside a backend API.
An API provides a clear boundary between the machine learning system and the rest of the application.
For example:
POST /predict
could accept:
{
  "age": 35,
  "income": 52000,
  "transactions": 18
}
and return:
{
  "prediction": 0,
  "probability": 0.91
}
The frontend does not need to know how the model works internally.
It only needs to understand the API contract.
This separation provides several advantages:
- The frontend can be built with React, Vue, Angular, or another framework.
- The model can be written in Python.
- The model can be updated without rewriting the frontend.
- Authentication can be implemented at the API layer.
- Monitoring can be added around inference requests.
- Multiple applications can consume the same model API.
Choosing the Right Model Format
Before deploying a model, consider how it will be serialized and loaded.
Different machine learning frameworks have different approaches.
Common options include:
- Pickle-based Python serialization
- Joblib
- ONNX
- TensorFlow SavedModel
- PyTorch model formats
- Framework-specific deployment formats
The correct choice depends on the model, runtime environment, and deployment requirements.
For example, ONNX can be useful when portability across supported runtimes is important. A Python-native format may be convenient when the entire inference service already uses the same Python ecosystem.
The most important rule is consistency.
The production environment should use compatible versions of the libraries and preprocessing components required by the model.
Build a Dedicated Inference API
Python is a natural choice for many machine learning APIs because much of the machine learning ecosystem is built around Python.
FastAPI is one option for building an inference service. Its documentation describes it as a Python framework for building APIs using standard Python type hints, and it provides automatic OpenAPI documentation. FastAPI also specifically documents its suitability for machine learning web APIs, including concurrency and parallelism considerations.
A minimal API might look like this:
from fastapi import FastAPI
from pydantic import BaseModel
import joblib

app = FastAPI()

model = joblib.load("model.joblib")


class PredictionRequest(BaseModel):
    age: float
    income: float
    transactions: int


@app.post("/predict")
def predict(data: PredictionRequest):
    features = [[
        data.age,
        data.income,
        data.transactions
    ]]

    prediction = model.predict(features)[0]

    return {
        "prediction": int(prediction)
    }
This example demonstrates an important production principle: load the model when the application starts rather than loading it for every request.
Loading a large model repeatedly can add unnecessary latency and consume significant resources.
FastAPI also automatically generates interactive API documentation through OpenAPI-based tooling, which can make testing and integration easier during development.
Connect the Frontend to the ML API
Once the model-serving API is available, a JavaScript frontend can communicate with it using HTTP.
For example:
async function getPrediction(input) {
  const response = await fetch("/api/predict", {
    method: "POST",
    headers: {
      "Content-Type": "application/json"
    },
    body: JSON.stringify(input)
  });

  if (!response.ok) {
    throw new Error("Prediction request failed");
  }

  return response.json();
}
The frontend can then display the result:
const result = await getPrediction({
  age: 35,
  income: 52000,
  transactions: 18
});

console.log(result.prediction);
The frontend does not need to understand the internal machine learning algorithm.
That is a major advantage of the API architecture.
Keep Preprocessing Consistent
One of the easiest ways to break a machine learning application is to change preprocessing between training and production.
Suppose a model was trained with:
age
income
transactions
where income was normalized and categorical values were encoded in a specific way.
If the production API sends raw or differently encoded values, the model may produce unreliable predictions even though the API itself appears to work correctly.
The solution is to treat preprocessing as part of the model pipeline.
Instead of thinking:
Model = trained algorithm
think:
Production model =
Preprocessing + Feature Transformation + Model + Postprocessing
The exact same transformations used during training should be reproduced during inference.
This is especially important when working with:
- Standardization
- Normalization
- One-hot encoding
- Tokenization
- Image resizing
- Feature selection
- Missing-value handling
- Text preprocessing
Validate User Input Before Inference
Never assume that incoming data is valid.
A public API can receive:
- Missing values
- Incorrect data types
- Extremely large values
- Negative values where they make no sense
- Unexpected strings
- Malformed JSON
Input validation should happen before data reaches the model.
With FastAPI and Pydantic, developers can define structured request models:
from pydantic import BaseModel, Field


class PredictionRequest(BaseModel):
    age: float = Field(gt=0, lt=120)
    income: float = Field(ge=0)
    transactions: int = Field(ge=0)
This creates a clear contract for the API.
Validation also improves reliability because the model receives data in a predictable format.
Handle Errors Gracefully
Machine learning inference can fail for many reasons.
For example:
- The model file may be unavailable.
- Input preprocessing may fail.
- A required feature may be missing.
- A dependency may be incompatible.
- The model may receive an unexpected data type.
The API should return useful HTTP responses without exposing sensitive internal information.
For example:
from fastapi import HTTPException


@app.post("/predict")
def predict(data: PredictionRequest):
    try:
        features = [[
            data.age,
            data.income,
            data.transactions
        ]]

        prediction = model.predict(features)[0]

        return {"prediction": int(prediction)}

    except Exception:
        raise HTTPException(
            status_code=500,
            detail="Prediction service temporarily unavailable"
        )
In a real production application, the full exception should be recorded in secure server logs while the client receives a controlled error message.
Optimize Machine Learning Inference
Model accuracy is only one part of the user experience.
A prediction that takes several seconds may make an otherwise excellent web application feel slow.
Latency can come from several places:
Browser
   ↓
Network
   ↓
API
   ↓
Preprocessing
   ↓
Model inference
   ↓
Postprocessing
   ↓
Network
   ↓
Browser
To reduce latency, developers can consider several strategies.
Load the Model Once
Avoid loading the model on every request.
Load it during application startup or worker initialization.
Reduce Input Processing
Avoid unnecessary transformations.
If preprocessing takes a significant portion of the request time, profile it and optimize the expensive operations.
Use an Appropriate Model
A larger model is not always the best model for a web application.
A slightly less complex model that provides similar accuracy but dramatically lower latency may produce a better overall user experience.
Batch Requests When Appropriate
For applications processing many predictions simultaneously, batching can improve hardware utilization.
However, batching is most useful for workloads where small amounts of additional waiting time are acceptable.
Real-time interactive applications often require different strategies.
Synchronous vs Asynchronous Inference
Not every machine learning task should be handled as a normal request-response operation.
Consider two examples.
Real-Time Prediction
A user enters information and expects an answer immediately.
Request → Model → Response
This is suitable for relatively fast models.
Examples include:
- Classification
- Small recommendation models
- Simple regression
- Basic text analysis
Long-Running Prediction
A user uploads a large document or video that requires substantial processing.
In this situation, keeping an HTTP request open for a long time may be inefficient.
A better architecture can be:
Upload
  ↓
Create Job
  ↓
Background Worker
  ↓
ML Processing
  ↓
Store Result
  ↓
Notify User
The frontend can periodically check the job status or receive an update through another mechanism.
This architecture is more appropriate for computationally expensive workloads.
Use Background Workers for Heavy ML Tasks
Heavy inference should not automatically run inside the same process responsible for handling every web request.
Depending on the workload, teams may separate:
- API servers
- Model servers
- Background workers
- Job queues
- Databases
- Object storage
This allows each component to scale independently.
For example:
                 ┌──────────────┐
                 │   Frontend   │
                 └──────┬───────┘
                        │
                        ▼
                 ┌──────────────┐
                 │   API Layer  │
                 └──────┬───────┘
                        │
              ┌─────────┴─────────┐
              ▼                   ▼
       ┌─────────────┐     ┌─────────────┐
       │ Fast Inference│     │ Job Queue   │
       │    Model     │     └──────┬──────┘
       └─────────────┘            │
                                  ▼
                           ┌─────────────┐
                           │ ML Worker   │
                           └─────────────┘
The exact architecture depends on the application.
Deploying an ML-Powered Web Application
Deployment means making the application available to users through production infrastructure.
FastAPI’s deployment documentation describes several approaches, including self-managed servers, cloud services, containers, and other deployment strategies.
A typical production architecture might contain:
                 Internet
                    │
                    ▼
             ┌─────────────┐
             │ Load Balancer│
             └──────┬──────┘
                    │
             ┌──────▼──────┐
             │ Web / API   │
             │   Server    │
             └──────┬──────┘
                    │
             ┌──────▼──────┐
             │ ML Inference│
             │   Service   │
             └──────┬──────┘
                    │
             ┌──────▼──────┐
             │ Model Files │
             └─────────────┘
Containers can make this architecture easier to reproduce because the application, dependencies, and runtime environment can be packaged together.
FastAPI also distinguishes development execution from production execution; its documentation recommends production-oriented execution without development auto-reload.
Secure the Machine Learning API
A machine learning endpoint is still a web API, so normal application security practices apply.
Important protections include:
- HTTPS
- Authentication
- Authorization
- Rate limiting
- Input validation
- Secure secrets management
- Dependency updates
- Logging
- Monitoring
- CORS configuration where appropriate
Do not assume that an ML endpoint is safe simply because it only returns predictions.
Attackers may attempt to abuse the endpoint by sending excessive requests, malformed inputs, or carefully constructed data.
For models that process sensitive information, privacy requirements become even more important.
Protect Model Files
A trained model can represent significant intellectual property.
If the model is proprietary, avoid exposing the model file directly to the browser.
A safer architecture is:
Browser → API → Private Model
rather than:
Browser → Download Model
Keeping the model server-side also allows you to control access and update the model without forcing every user to download a new version.
Monitor Model Performance
Traditional application monitoring is not enough for machine learning systems.
A normal API might monitor:
- Response time
- HTTP errors
- CPU usage
- Memory usage
- Request volume
An ML application should also monitor model-specific metrics.
Examples include:
- Prediction distribution
- Input feature distribution
- Confidence scores
- Model latency
- Prediction errors
- Data drift
- Model accuracy when ground truth becomes available
This is important because a model can remain technically operational while becoming less useful.
For example, a recommendation model trained on historical user behavior may perform differently as user preferences change.
Detect Data Drift
Machine learning models rely on assumptions about their input data.
If the real-world distribution changes significantly, model performance can deteriorate.
Suppose a model was trained using customer behavior from one period:
Training Data
↓
Model
↓
Predictions
Months later, customer behavior may change:
New Data
↓
Different Distribution
↓
Potentially Lower Model Performance
This is called data drift.
Monitoring input distributions can help teams identify situations where a model may need investigation or retraining.
Version Your Models
Treat models as versioned production artifacts.
For example:
model-v1
model-v2
model-v3
A production system should be able to identify which model generated a prediction.
An API response might internally record:
{
  "prediction": 1,
  "model_version": "v3"
}
This makes debugging easier.
If users report unexpected predictions, engineers can determine which model version was responsible.
Use CI/CD for Machine Learning Applications
Machine learning applications benefit from automated deployment pipelines.
A basic pipeline could look like:
Code Change
   ↓
Automated Tests
   ↓
Build
   ↓
Model Validation
   ↓
Security Checks
   ↓
Deploy to Staging
   ↓
Evaluation
   ↓
Production
This reduces the risk of manually deploying inconsistent environments.
Model files, preprocessing code, dependencies, API code, and configuration should be managed systematically.
When Should You Run the Model in the Browser?
Not every model needs a backend API.
Some lightweight models can potentially run directly in the browser.
Client-side inference can provide advantages such as:
- Reduced server requests
- Lower backend costs
- Potentially improved privacy for suitable workloads
- Offline functionality
- Immediate local inference
However, browser inference also has limitations.
Large models may consume significant memory and processing resources. Different devices may have very different performance characteristics.
Client-side deployment also exposes the model to the user, which may be undesirable for proprietary models.
Therefore, the decision should be based on model size, privacy requirements, latency, device capabilities, and intellectual property considerations.
API-Based vs Browser-Based Machine Learning
A simple comparison looks like this:
| Feature | API-Based ML | Browser-Based ML |
|---|---|---|
| Model privacy | Stronger | Lower |
| Server resources | Higher | Lower |
| Offline capability | Limited | Potentially strong |
| Large models | Better suited | Often difficult |
| Centralized updates | Easy | More complex |
| Device dependency | Lower | Higher |
Neither architecture is universally better.
The correct choice depends on the application.
Common Mistakes to Avoid
Loading the Model for Every Request
This wastes resources and increases latency.
Mixing Training and Production Code
Training pipelines and inference services should generally be separated.
Ignoring Preprocessing
A model can fail silently when production preprocessing differs from training.
Returning Internal Errors
Never expose stack traces or sensitive configuration information to public users.
Skipping Validation
Malformed input can cause errors and unexpected behavior.
Ignoring Monitoring
An API can return HTTP 200 responses while the model’s real-world performance deteriorates.
Deploying Without Versioning
Without model versions, investigating production predictions becomes much harder.
Optimizing Only for Accuracy
A model with excellent accuracy but unacceptable latency may be unsuitable for an interactive web application.
A Practical Architecture for Modern ML Web Applications
For many applications, the following architecture provides a useful starting point:
                 ┌─────────────────┐
                 │     Browser     │
                 │ React / Vue/etc │
                 └────────┬────────┘
                          │ HTTPS
                          ▼
                 ┌─────────────────┐
                 │    API Layer    │
                 │    FastAPI      │
                 └────────┬────────┘
                          │
              ┌───────────┴───────────┐
              ▼                       ▼
       ┌─────────────┐         ┌─────────────┐
       │ Validation  │         │ Authentication│
       └──────┬──────┘         └─────────────┘
              │
              ▼
       ┌─────────────┐
       │ Preprocess  │
       └──────┬──────┘
              │
              ▼
       ┌─────────────┐
       │ ML Model    │
       │ Inference   │
       └──────┬──────┘
              │
              ▼
       ┌─────────────┐
       │ Postprocess │
       └──────┬──────┘
              │
              ▼
       ┌─────────────┐
       │ JSON Result │
       └──────┬──────┘
              │
              ▼
            Browser
For larger systems, additional components such as queues, caches, databases, object storage, dedicated model servers, and monitoring systems can be introduced as needed.
Final Thoughts
Integrating machine learning into a web application is no longer an experimental concept. Developers can build production systems where a browser communicates with an API, the backend prepares the input, a trained model performs inference, and the application returns an intelligent result.
The most important part is not simply connecting a model to an endpoint.
A reliable ML-powered application needs a complete engineering strategy covering:
- Model serialization
- API design
- Input validation
- Consistent preprocessing
- Inference performance
- Authentication
- Security
- Deployment
- Monitoring
- Model versioning
- Data drift
- Continuous improvement
For many Python-based applications, FastAPI provides a practical foundation for exposing machine learning functionality through HTTP APIs, with automatic OpenAPI documentation and features suited to API development and ML workloads.
The goal should be to make machine learning feel like a normal part of the application architecture rather than a separate experimental component.
When the model, API, frontend, infrastructure, and monitoring systems are designed together, machine learning can become a reliable product feature capable of delivering real value to users.
Frequently Asked Questions
How do I integrate a machine learning model into a web application?
The most common approach is to expose the trained model through a backend API. The frontend sends input data to the API, the backend validates and preprocesses it, the model generates a prediction, and the API returns the result as JSON.
Which programming language is best for serving machine learning models?
Python is widely used because many machine learning frameworks and libraries are built around it. Frameworks such as FastAPI can be used to expose Python-based models through APIs.
Can I use a machine learning model with React?
Yes. React can communicate with a machine learning backend through HTTP APIs. The React application handles the user interface while the backend performs model inference.
Should machine learning models run on the frontend or backend?
It depends on the application. Small models may be suitable for browser-based inference, while large or proprietary models are often better kept on a backend or dedicated inference service.
How can I reduce machine learning API latency?
Start by measuring the entire request path. Common improvements include loading models once, optimizing preprocessing, choosing an appropriate model size, batching suitable workloads, using efficient runtimes, and separating long-running jobs from real-time requests.
How do I secure an ML prediction API?
Use HTTPS, authentication, authorization, input validation, rate limiting, secure secrets management, dependency updates, and appropriate monitoring. Keep proprietary model files on trusted server infrastructure when they should not be publicly distributed.
What is model drift?
Model or data drift occurs when the real-world data distribution changes compared with the data used during model development. Monitoring input and prediction patterns can help identify when a model may require investigation or retraining.
Can machine learning models be deployed with Docker?
Yes. Containerizing the inference service can make the runtime environment more reproducible and simplify deployment across development, staging, and production environments.
Sources and Further Reading
- FastAPI official documentation — API development, validation, OpenAPI, deployment, and machine-learning workloads.
- FastAPI documentation — Concurrency and parallelism for web and machine learning applications.
- FastAPI deployment documentation — Production deployment concepts and strategies.
- FastAPI frontend documentation — Integrating frontend applications with FastAPI services.
Last updated: August 2026
Leave a Reply